Why Low CPU Doesn’t Mean an EC2 Instance Is Right-Sized
Low CPU doesn’t mean an instance is oversized. Check memory, network, disk I/O, and burst credits before you shrink an EC2 instance.
Patrick · Founder of CloudBudgie
5 min read
An EC2 instance averages 8% CPU. Obviously oversized, right?
Maybe. But shrink it on that number alone and a cheap optimization can turn into an expensive incident.
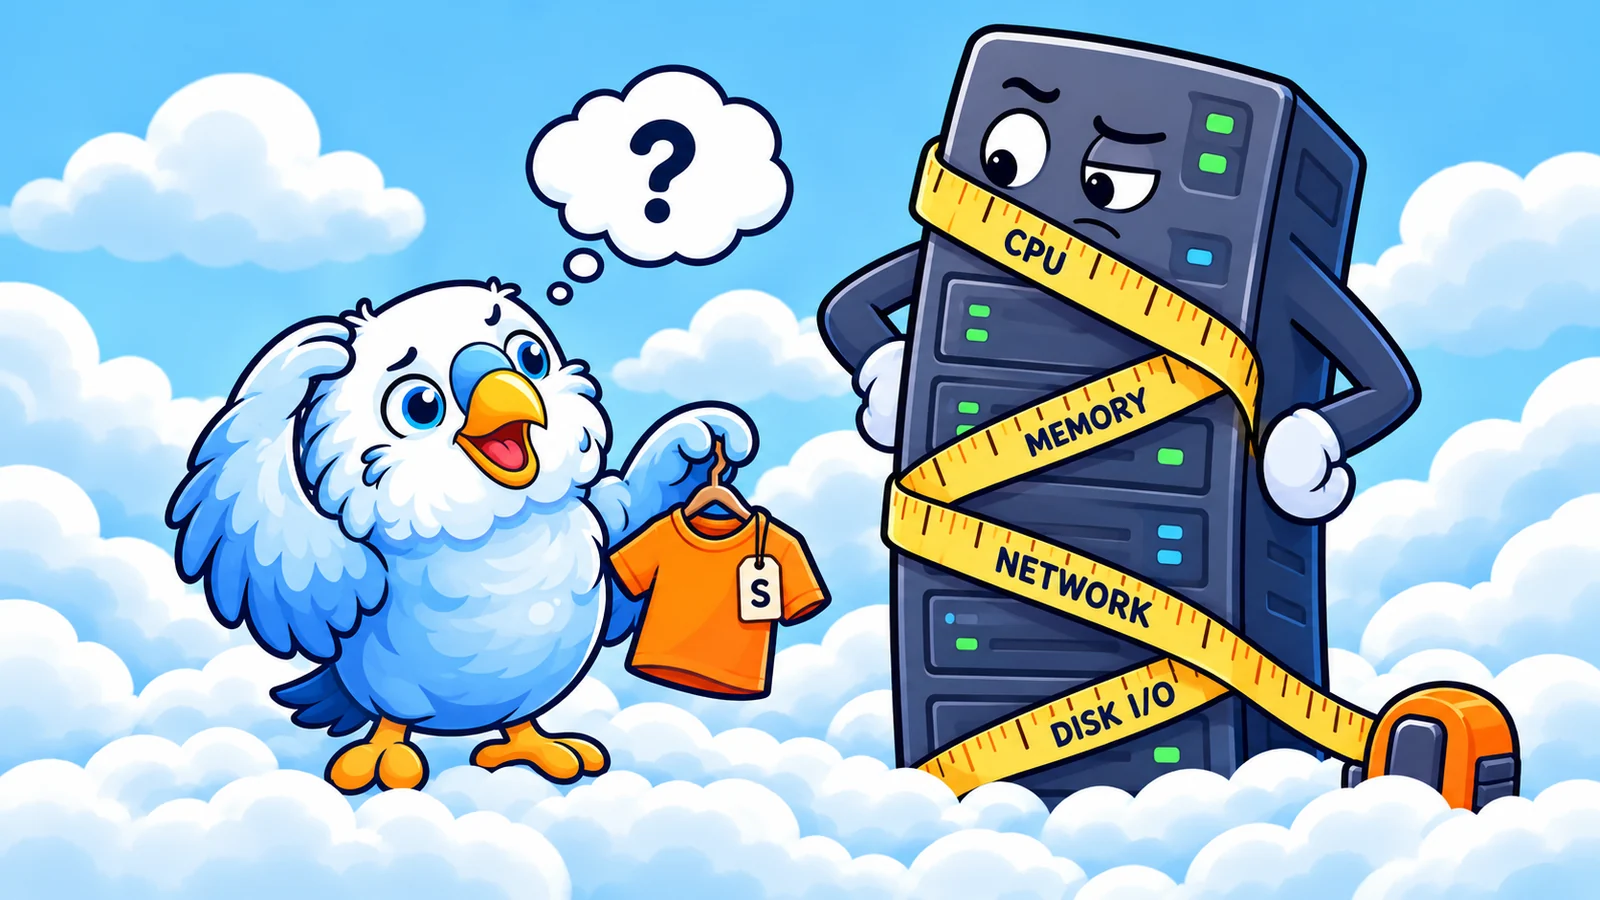
Sizing an instance on CPU alone is like buying a shirt by measuring only the sleeves. Average CPU is a fine place to start. It just isn't the whole story. It says nothing about memory, network, or storage, and it hides the moments your workload actually works hard.
A quiet CPU doesn't mean a quiet workload.
Averages hide the moments that matter
An average squashes a whole day into one number. A server can idle for hours and still need every bit of its capacity for a nightly batch job, a deploy, or a traffic spike.
So before you pick a smaller instance, look at the peaks: busy stretches, recurring jobs, and seasonal patterns. CloudWatch will give you percentiles like p95 and p99 alongside the average:
aws cloudwatch get-metric-statistics \
  --namespace AWS/EC2 --metric-name CPUUtilization \
  --dimensions Name=InstanceId,Value=i-0123456789abcdef0 \
  --start-time 2026-10-01T00:00:00Z --end-time 2026-10-15T00:00:00Z \
  --period 3600 --extended-statistics p95 p99 \
  --query 'Datapoints[].[Timestamp,ExtendedStatistics.p95,ExtendedStatistics.p99]' \
  --output text | sort
Look at more than a day, too. A business app might be dead quiet on weekends and slammed at month-end. Size for the busy times, because that's what the new instance has to handle, not the average.
Memory is often the real constraint
Here's one that catches a lot of teams: the default EC2 metrics in CloudWatch don't include memory. The hypervisor can't see inside the guest operating system. To measure memory, you need the CloudWatch agent or another monitoring tool running on the instance.
That creates a classic blind spot. CPU is low, memory is nearly full, and nobody can see it. Halve the instance size and you usually halve the memory too. Hello, swapping, garbage-collection pressure, and out-of-memory crashes.
Check used and available memory, swap, and app-level signals like heap usage. Sometimes the right move isn't a smaller instance at all, it's a different family. A memory-optimized instance with fewer vCPUs can fit a low-CPU, high-memory workload better than a smaller general-purpose one.
Network and storage have limits too
Every instance family and size comes with its own network bandwidth, packet rates, and EBS bandwidth and IOPS limits. Plenty of smaller sizes list bandwidth as "up to" a number. They can burst to it for a while, but they can't hold it.
If your app spends its time waiting on a database, a disk, or a remote API, CPU stays low while the real bottleneck sits somewhere else. Shrink the instance and you can make that bottleneck worse.
Compare your workload's peak throughput, I/O, and latency against the documented limits of the instance you're considering. And remember that EBS performance depends on both the volume and the instance. A fast volume can't help if the instance can't drive it.
Burstable instances add another wrinkle
Burstable instances like the T family earn CPU credits while they run below a baseline and spend them above it. A workload that looks quiet on average might be living on those bursts.
Check the CPUCreditBalance and CPUCreditUsage metrics, and know which mode the instance runs in. In standard mode, an instance that runs out of credits gets held to its baseline. In unlimited mode it can keep bursting, but if average CPU stays above the baseline over a rolling 24-hour window, you pay for surplus credits. So a burstable instance that looks cheaper on paper can end up costing more, or running slower, under sustained load.
Architecture and compatibility are part of the price
Moving to a newer generation or a Graviton (Arm-based) instance can be a great move. Just check compatibility first: operating system images, native dependencies, container images built for a single architecture, agents and drivers, and commercial software licensed per vCPU or tied to a processor type.
The cheapest hourly price isn't automatically the cheapest decision. Engineering time, deployment risk, and performance all count.
The cheapest instance is the one that meets the workload's real requirements—not the one with the smallest price tag.
CPU
Peaks, percentiles, and CPU credits, not only the average
Default EC2 metric
Memory
Used and available memory, swap, and out-of-memory events
Needs the CloudWatch agent or another collector
Network
Throughput and packet rates at peak
Default EC2 metric
Storage I/O
IOPS, throughput, and latency against volume and instance limits
EC2 and EBS metrics
Then every gate must pass
- Peak demand
- Architecture and licensing
- Test and rollback plan
Candidate instance type
A safer way to rightsize
- Baseline. Record utilization, latency, error rates, throughput, and cost over a representative period, busy times included.
- Shortlist. Pick candidate types that meet your CPU, memory, network, storage, and architecture needs, not just the cheapest one.
- Test. Try the change somewhere lower-risk first, with realistic peak load.
- Ship it through review. Make the change through your normal approval and deployment process, with a rollback plan ready.
- Watch. Keep an eye on the workload afterward. If your infrastructure lives in Terraform or CloudFormation, make the change there so your code and reality stay in sync.
An optimization only counts if the app still performs afterward.
What a good recommendation explains
A rightsizing recommendation should show its work. What was measured, and what wasn't. The proposed instance type and the expected cost difference. The constraints that matter, and how to validate the change.
That's a higher bar than "CPU is low, downsize now." But it's a lot more useful to the engineer who's on the hook for production.
It's the bar I hold CloudBudgie to. Its EC2 rightsizing recommendations show the utilization evidence behind each one, including memory when the instance reports it, along with a confidence level and the estimated monthly savings. Then you decide how to act: apply a supported change directly, or have BudgieBot open a Terraform or CloudFormation pull request for your team to review.
References
- List the available CloudWatch metrics for your instances
- Collect metrics with the CloudWatch agent
- CloudWatch statistics definitions (percentiles)
- Burstable performance instances: unlimited mode concepts
- Amazon EBS volume performance
- Amazon EBS-optimized instances
- Amazon EC2 instance network bandwidth
- AWS Graviton technical guide